Public datasets arrive with different schemas, identifiers, and refresh cycles. CLOUDSUFI built repeatable workflows to ingest, validate, and connect them at scale, with human review for matching exceptions.
Google Data Commons aggregates and publishes datasets from governments, research institutions, and other organizations, including census, climate, economic, and health data. Sources arrive with different schemas, identifiers, and refresh schedules. Importing and refreshing them at scale required consistent validation and monitoring.
Entity matching added another constraint: the same place, variable, or statistical concept could be named or formatted differently across datasets. As source volume grew, manual reconciliation and one-off handling consumed more engineering time.
CLOUDSUFI’s contribution was the engineering and workflow layer used to make recurring Data Commons operations more scalable. The team developed repeatable processes for dataset ingestion and refreshes, automated validation and monitoring, supported schema mapping, and introduced AI-assisted entity resolution with human review for exceptions.
These capabilities were integrated with the Data Commons knowledge graph and data infrastructure. Together, they gave the team a more consistent way to onboard new datasets, maintain existing sources, and review relationships across differently structured data.
CLOUDSUFI built three connected capabilities. Schema-mapping workflows aligned new source structures with the existing graph. AI-assisted entity resolution matched statistical variables and place identifiers across sources, with human review for exceptions. An event-driven update process kept the graph current as datasets changed.
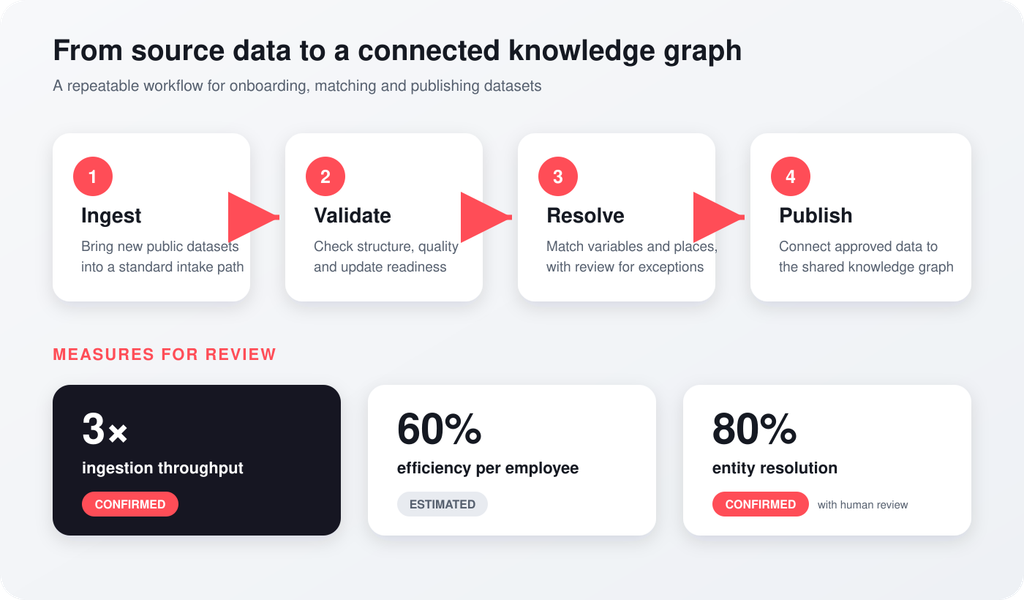
The latest delivery review confirms a 3× increase in data-ingestion throughput and 80% entity-resolution performance. The 60% efficiency-per-employee figure is an estimate based on import and refresh volumes.
The delivery model uses consistent validation, monitoring, schematization, and entity-review workflows for dataset imports and refreshes. Engineers begin with a defined process for exceptions and quality checks instead of recreating it for each source.
“CLOUDSUFI brings a rare combination of strategic data expertise and execution excellence. Their team understands the complete data journey – from sourcing and governance to discovery and monetization. Rather than simply deploying technology, they focus on making data usable, trusted, and valuable across the organization. That end-to-end perspective, combined with their specialized approach to organizing and operationalizing enterprise data, made them an invaluable partner.”
Deepinder DhuriaProduct Manager, Google Data Commons
“CLOUDSUFI has been an effective partner for Data Commons, supporting large-scale data ingestion, automation, and managed services. Their team demonstrated strong technical expertise in building scalable validation, monitoring, and schematization tools, consistently improving data reliability and throughput. Given their disciplined execution on critical projects, I expect CLOUDSUFI to play a key role in scaling Data Commons 10x over the next 12-18 months.”
Randeep ToorSenior TPM, Data Commons · Google
The team is extending the knowledge graph into cross-domain analysis across climate, economic, and health datasets, while continuing to onboard new sources and expand natural-language querying.
Let's build what's next.
Talk to us about your data and AI challenges — and how CLOUDSUFI can help solve them.
Talk to us →