Agency data sat in separate systems with different schemas and identifiers. Working alongside Google’s core team, CLOUDSUFI established a common model and repeatable validation process to support phased onboarding across the wider program.
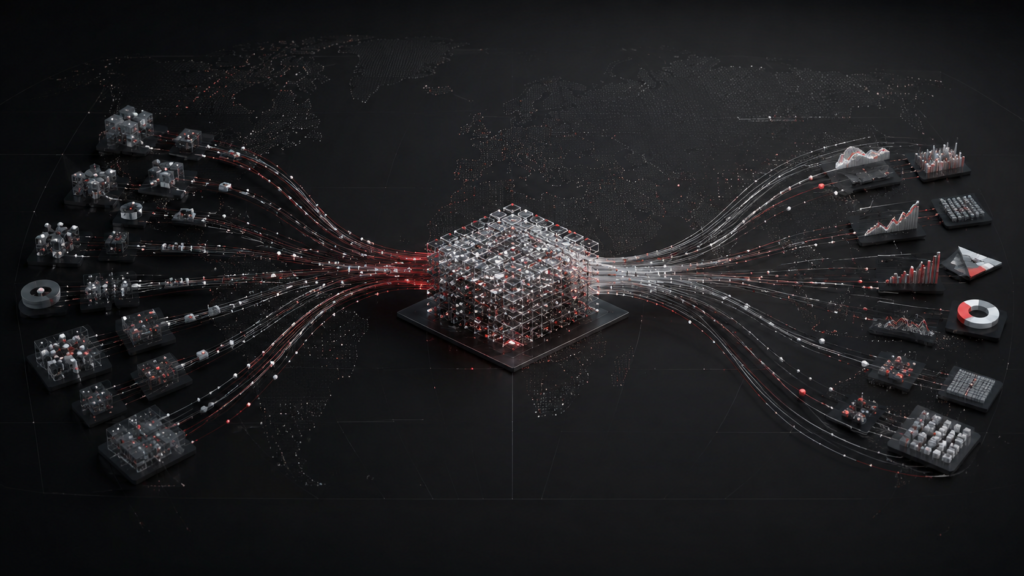
Statistical and development data was distributed across agency systems with different levels of maturity, quality, and schema design. Identifiers, refresh schedules, and field structures also varied by source. There was no shared platform for discovering or analyzing data across agencies.
The program needed a common model without requiring every agency to replace its source environment. It also needed a repeatable agency onboarding method. Agency teams needed enough documentation to operate the process after handover.
“A repeatable onboarding pipeline gives each agency a clearer path from its existing data structure to a shared model. Each new dataset can follow an established process instead of starting from scratch.”
Randeep ToorGoogle Data Commons PM
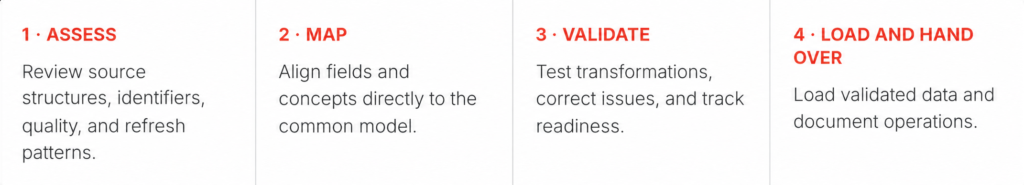
Embedded alongside Google’s core team, CLOUDSUFI supported schema mapping, data processing, pipeline development, cloud deployment, and enablement. The team first explored automated mapping. It then switched to direct mapping when automation did not meet the program’s technical needs. This kept the work tied to validated source structures.
Operating documentation and enablement support future agency-led onboarding and platform ownership.
A configurable interface and conversational-agent blueprint were reviewed with stakeholders. Separately, CLOUDSUFI demonstrated a proof-of-concept natural-language agent for the UNDP Risk Anticipation Data track. The demonstration took place in Stockholm on June 15–16. The concept grounded responses in the underlying risk data and applied custom geographic logic. It was not implemented or deployed for UNDP.
“The shared model makes development and risk data easier to discover while giving UN teams the documentation and operating knowledge needed to manage the platform themselves.”
Randeep ToorGoogle Data Commons PM
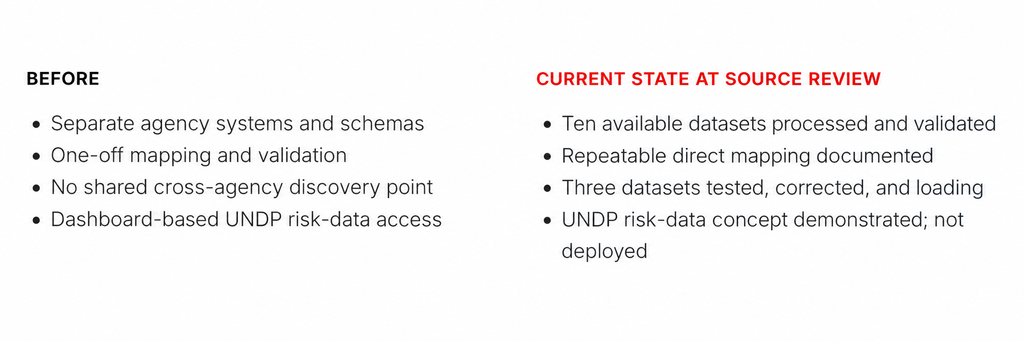
The work remains a rollout story rather than a completed transformation. The source material did not include a validated cost saving or time-reduction percentage, so this case study does not claim one.
CLOUDSUFI combines data engineering, AI, and cloud delivery to standardize complex data environments. The work also transfers operating knowledge to internal teams.
Let's build what's next.
Talk to us about your data and AI challenges — and how CLOUDSUFI can help solve them.
Talk to us →